Automated 3D Landmarking Pipeline
I built this workflow to propose pelvic landmarks from CT and 3D scans, so anatomists can focus on checking the placements.
Across 39 adult pelves, 83% of automatically placed landmarks fell within 2 mm of expert-corrected placements and 97% within 4 mm. Shape analysis closely agreed with the expert-corrected analysis (about 5% measurement error).
114 specimens in 4 h 34 min in one automated batch, before anatomical review.
Three landmarking experiments
These are three separate experiments, each against its own reference. The fusion evaluation describes the latest research configuration.
- Registration benchmark
- 11.38 → 5.86 mm mean landmark error, from one deformable template to 12-template consensus.
- 13 annotated specimens · 156 leave-one-out registrations · hand-placed references
- Landmark and shape agreement
- 83% within 2 mm and 97% within 4 mm of expert-corrected placements.
- 39 adult pelves · about 5% shape measurement error
- Surface sample-size experiment
- 2.53 mm mean distance with 20 annotated training and template cases, 0.21 mm above the full surface reference.
- 12 held-out cases · observer-corrected references · registration and DiffusionNet
How it works
TotalSegmentator produces bone masks from CT. I transfer landmarks from multiple templates with PyTorch/CUDA and fuse them with predictions from a 3D U-Net and DiffusionNet I trained. The app checks units and orientation, then flags disagreements for anatomical review.
Registration benchmark
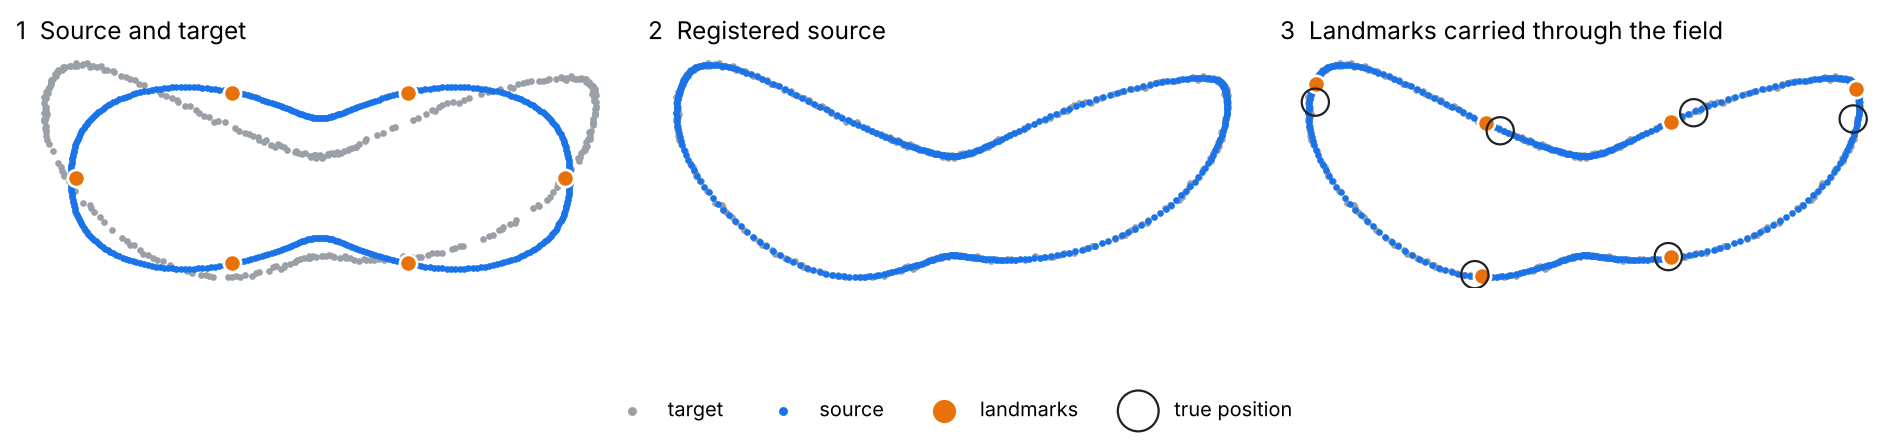
In the leave-one-out benchmark, mean error was 13.48 mm with rigid single-template registration, 11.38 mm with deformable refinement and 5.86 mm with 12-template consensus.
At 3,000 points and 150 iterations, the deformable step took 118.7 s in NumPy, 50.6 s in PyTorch on CPU and about 2 s on an RTX 4080 SUPER.
15 November 2026 · Unpublished analysis
How closely did the landmarks and shape analysis agree?
Across 2,496 landmarks on 39 adult pelves, 82.5% were within 2 mm of the reference and 96.6% were within 4 mm. Shape measurement error was 5.2% in a Procrustes ANOVA of the automatic and reference configurations.
The 39 cases were held out of training and the template library. The expert established the reference by correcting earlier automated placements. An independent evaluation would start with landmarks placed from scratch.
Compare pointwise distances by method
| Method | Mean (mm) | Median (mm) | Count >10 mm |
|---|---|---|---|
| Three-method fusion | 1.33 | 0.87 | 10 |
| Registration + surface model | 1.74 | 1.28 | 10 |
| DiffusionNet surface model | 1.86 | 1.43 | 10 |
| 3D U-Net on CT | 1.95 | 1.60 | 4 |
| ALPACA registration | 3.86 | 3.08 | 109 |
Fusion had the lowest mean. The CT model alone had fewer distances over 10 mm.
4–5 November 2026 · Separate exploratory experiment
How far can 20 annotated cases take you?
With 20 annotated training and template cases, surface registration plus DiffusionNet averaged 2.53 mm on 12 held-out cases, 0.21 mm above the full surface configuration (2.32 mm with 24 templates and 83 training cases).
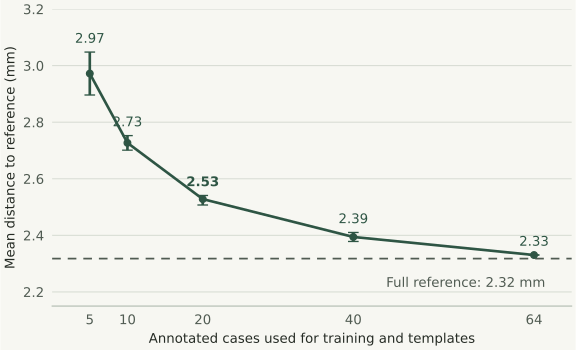
View exact chart values and draw counts
| Annotated cases | Draws | Mean (mm) | Draw range (mm) |
|---|---|---|---|
| 5 | 2 | 2.97 | 2.90–3.05 |
| 10 | 2 | 2.73 | 2.70–2.75 |
| 20 | 3 | 2.53 | 2.51–2.54 |
| 40 | 2 | 2.39 | 2.38–2.41 |
| 64 | 1 | 2.33 | — |
| Full reference | 1 | 2.32 | — |
The CT model averaged 5.72 mm at 20 cases in its one 12,000-step run, and 4.30 mm in a longer run at the same sample size.
What if fewer landmarks are annotated per case?
In a single draw at 20 cases, teaching DiffusionNet only 40 landmarks changed the mean by −0.02 mm compared with teaching all 64 and scoring both models on the same 40 landmarks. Teaching only 10 increased the mean by 0.62 mm on the matched 10 landmarks. Both were subsets of the same pelvic protocol.
This was one 64-landmark protocol on female pelves with one observer. Test cases were excluded from training and templates, had been seen in earlier development and were scored against observer-corrected references.
Source data for both November evaluations: The Free Access Decedent Database funded by the National Institute of Justice grant number 2016-DN-BX-0144.